
ZYREX APEX LITE — Mini AI Workstation
Your Personal AI. Right on Your Desk.
Powerful local AI for coding, research, documents, and everyday productivity. Private, personal, and always within reach.
Scroll to exploreMeet APEX LITE
A tiny box. A big AI brain.
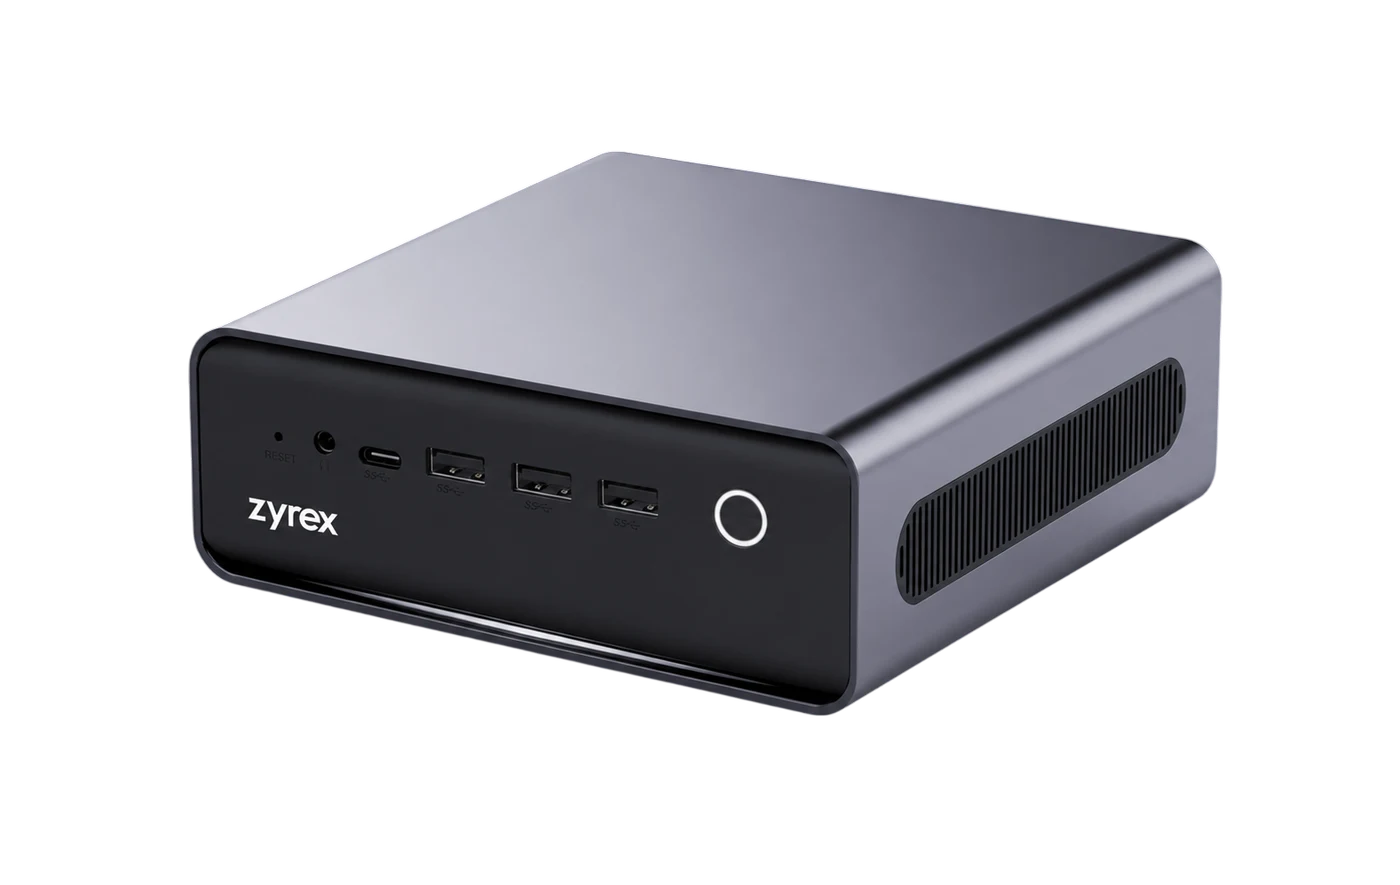
Meet APEX LITE, a compact AI workstation designed to bring intelligent computing directly to your desk.
A compact metal workstation designed to fit into modern workspaces.
Run supported local language models to assist with research, writing, programming, and document analysis.
Process information locally without sending AI inference requests to external cloud services. Privacy depends on configuration, connected tools, and network permissions.
Performance
Small in size. Serious about AI.
- Processor
- Intel Core Ultra X7 358H
- Memory
- 32GB LPDDR5X reference configuration; other capacities are validated before being offered
- Storage
- 3 × M.2 slots · reference 3 × 1TB · up to 2TB per slot (subject to validation)
- AI acceleration
- Integrated Intel graphics, Intel AI hardware and Intel NPU
- Networking
- Wi-Fi 6E · Bluetooth 5.2 · dual 2.5GbE LAN
- Power
- 150W power adapter
Reference configuration from the product document; final specifications are confirmed before release. NPU and graphics TOPS figures are not an indicator of language-model speed.
Why local AI
Your AI. Your data. Your control.
Keep supported AI inference and document processing on your own machine.
Run downloaded local models without paying an external AI provider for every generated token. Hardware, electricity, maintenance and optional cloud services can still cost money.
Use previously downloaded local models without an internet connection. Online research, messaging integrations, updates and cloud tools still need network access.
AI Models
Find the right AI model for your desk.
Only models that run on the 32GB memory of APEX LITE are shown. Larger models belong to APEX.
Intel Core Ultra X7 358H · integrated Intel graphics · Intel NPU. Compact personal AI workstation. Planning assumes ~22 GB of 32 GB usable for weights + KV cache after OS and GPU reservations.
GPT-OSS 20B
OpenAI · MoEMXFP412 GBFits comfortably
OpenAI · MoEMXFP412 GBFits comfortably
- Developer
- OpenAI
- Architecture
- MoE (mixture of experts) · 20B params
- Recommended use
- Everyday assistant
- Evidence
- Estimated — not yet tested
- Runtime / version
- Not recorded
- Context length
- Not recorded
- Runs / test date
- Not recorded
- Verification
- Calculated estimate: generation ≈ 100 GB/s effective memory bandwidth ÷ weight size (dense) or scaled from the measured Qwen3 30B-A3B result (MoE). Prompt speed scaled from the measured Qwen3.6 35B-A3B result. Not measured on APEX LITE. StorageReview measured 18.3 tok/s for gpt-oss:20b in an Ollama coding-agent test on a Core Ultra X7 358H laptop (an end-to-end workload, not a pure decode benchmark). Planning estimate — not measured
Qwen3.5 9B
Qwen · DenseQ45.4 GBFits comfortably
Qwen · DenseQ45.4 GBFits comfortably
- Developer
- Qwen
- Architecture
- Dense · 9B params
- Recommended use
- Fast personal assistant
- Evidence
- Estimated — not yet tested
- Runtime / version
- Not recorded
- Context length
- Not recorded
- Runs / test date
- Not recorded
- Verification
- Calculated estimate: generation ≈ 100 GB/s effective memory bandwidth ÷ weight size (dense) or scaled from the measured Qwen3 30B-A3B result (MoE). Prompt speed scaled from the measured Qwen3.6 35B-A3B result. Not measured on APEX LITE. Planning estimate — not measured
Qwen3.5 9B
Qwen · DenseQ89.9 GBFits comfortably
Qwen · DenseQ89.9 GBFits comfortably
- Developer
- Qwen
- Architecture
- Dense · 9B params
- Recommended use
- Fast personal assistant
- Evidence
- Estimated — not yet tested
- Runtime / version
- Not recorded
- Context length
- Not recorded
- Runs / test date
- Not recorded
- Verification
- Calculated estimate: generation ≈ 100 GB/s effective memory bandwidth ÷ weight size (dense) or scaled from the measured Qwen3 30B-A3B result (MoE). Prompt speed scaled from the measured Qwen3.6 35B-A3B result. Not measured on APEX LITE. Planning estimate — not measured
Qwen3 8B
Qwen · DenseQ45 GBFits comfortably
Qwen · DenseQ45 GBFits comfortably
- Developer
- Qwen
- Architecture
- Dense · 8B params
- Recommended use
- Fast personal assistant
- Evidence
- Estimated — not yet tested
- Runtime / version
- Not recorded
- Context length
- Not recorded
- Runs / test date
- Not recorded
- Verification
- Calculated estimate: generation ≈ 100 GB/s effective memory bandwidth ÷ weight size (dense) or scaled from the measured Qwen3 30B-A3B result (MoE). Prompt speed scaled from the measured Qwen3.6 35B-A3B result. Not measured on APEX LITE. Planning estimate — not measured
Qwen3.6 35B-A3B
Qwen · MoEQ421 GBFits with constraints
Qwen · MoEQ421 GBFits with constraints
- Developer
- Qwen
- Architecture
- MoE (mixture of experts) · 35B params
- Recommended use
- Capable MoE assistant
- Evidence
- Third-party measurement
- Runtime / version
- Not recorded
- Context length
- Not recorded
- Runs / test date
- Not recorded
- Verification
- Third-party measurement — see source.
- Source
- grigio.org — llama.cpp on Intel Arc (Xiaomi Book Pro 14)
Core Ultra X7 358H, Arc B390, 30GiB unified memory, llama.cpp Vulkan, Qwen3.6-35B-A3B Q4_K_M fully offloaded to the GPU: 691 pp512, 32.7 tok/s generation. NoLlama OpenVINO INT4 reports 41.1 tok/s.
Third-party result on comparable hardware, not measured on a ZYREX unit. - Note
- Needs reduced context or specialised configuration.
Qwen3.8 27B Dense
Qwen · DenseQ417 GBFits with constraints
Qwen · DenseQ417 GBFits with constraints
- Developer
- Qwen
- Architecture
- Dense · 27B params
- Recommended use
- Higher-quality assistant
- Evidence
- Estimated — not yet tested
- Runtime / version
- Not recorded
- Context length
- Not recorded
- Runs / test date
- Not recorded
- Verification
- Calculated estimate: generation ≈ 100 GB/s effective memory bandwidth ÷ weight size (dense) or scaled from the measured Qwen3 30B-A3B result (MoE). Prompt speed scaled from the measured Qwen3.6 35B-A3B result. Not measured on APEX LITE. Planning estimate — not measured
- Note
- Needs reduced context or specialised configuration.
Qwen3 30B-A3B
Qwen · MoEQ418 GBFits with constraints
Qwen · MoEQ418 GBFits with constraints
- Developer
- Qwen
- Architecture
- MoE (mixture of experts) · 30B params
- Recommended use
- Fast, capable assistant
- Evidence
- Third-party measurement
- Runtime / version
- Not recorded
- Context length
- Not recorded
- Runs / test date
- Not recorded
- Verification
- Third-party measurement — see source.
- Source
- MetriLLM — Qwen3-30B on Core Ultra X7 358H
Ollama 0.32.14, Core Ultra X7 358H: 31.0 tok/s generation. OpenVINO INT4 on the same CPU/GPU reaches 52.7 tok/s (NoLlama community report, 64GB LPDDR5X-8533).
Third-party result on comparable hardware, not measured on a ZYREX unit. - Note
- Needs reduced context or specialised configuration.
Qwen3-Coder 30B-A3B
Qwen · MoEQ418 GBFits with constraints
Qwen · MoEQ418 GBFits with constraints
- Developer
- Qwen
- Architecture
- MoE (mixture of experts) · 30B params
- Recommended use
- Coding
- Evidence
- Estimated — not yet tested
- Runtime / version
- Not recorded
- Context length
- Not recorded
- Runs / test date
- Not recorded
- Verification
- Calculated estimate: generation ≈ 100 GB/s effective memory bandwidth ÷ weight size (dense) or scaled from the measured Qwen3 30B-A3B result (MoE). Prompt speed scaled from the measured Qwen3.6 35B-A3B result. Not measured on APEX LITE. Planning estimate — not measured
- Note
- Needs reduced context or specialised configuration.
DeepSeek-R1 Distill 8B
DeepSeek · DenseQ44.8 GBFits comfortably
DeepSeek · DenseQ44.8 GBFits comfortably
- Developer
- DeepSeek
- Architecture
- Dense · 8B params
- Recommended use
- Reasoning
- Evidence
- Estimated — not yet tested
- Runtime / version
- Not recorded
- Context length
- Not recorded
- Runs / test date
- Not recorded
- Verification
- Calculated estimate: generation ≈ 100 GB/s effective memory bandwidth ÷ weight size (dense) or scaled from the measured Qwen3 30B-A3B result (MoE). Prompt speed scaled from the measured Qwen3.6 35B-A3B result. Not measured on APEX LITE. Planning estimate — not measured
DeepSeek-R1 Distill 8B
DeepSeek · DenseQ88.8 GBFits comfortably
DeepSeek · DenseQ88.8 GBFits comfortably
- Developer
- DeepSeek
- Architecture
- Dense · 8B params
- Recommended use
- Reasoning
- Evidence
- Estimated — not yet tested
- Runtime / version
- Not recorded
- Context length
- Not recorded
- Runs / test date
- Not recorded
- Verification
- Calculated estimate: generation ≈ 100 GB/s effective memory bandwidth ÷ weight size (dense) or scaled from the measured Qwen3 30B-A3B result (MoE). Prompt speed scaled from the measured Qwen3.6 35B-A3B result. Not measured on APEX LITE. Planning estimate — not measured
DeepSeek-R1 Distill 14B
DeepSeek · DenseQ48.4 GBFits comfortably
DeepSeek · DenseQ48.4 GBFits comfortably
- Developer
- DeepSeek
- Architecture
- Dense · 14B params
- Recommended use
- Reasoning
- Evidence
- Estimated — not yet tested
- Runtime / version
- Not recorded
- Context length
- Not recorded
- Runs / test date
- Not recorded
- Verification
- Calculated estimate: generation ≈ 100 GB/s effective memory bandwidth ÷ weight size (dense) or scaled from the measured Qwen3 30B-A3B result (MoE). Prompt speed scaled from the measured Qwen3.6 35B-A3B result. Not measured on APEX LITE. Planning estimate — not measured
DeepSeek-R1 Distill 14B
DeepSeek · DenseQ815 GBFits comfortably
DeepSeek · DenseQ815 GBFits comfortably
- Developer
- DeepSeek
- Architecture
- Dense · 14B params
- Recommended use
- Reasoning
- Evidence
- Estimated — not yet tested
- Runtime / version
- Not recorded
- Context length
- Not recorded
- Runs / test date
- Not recorded
- Verification
- Calculated estimate: generation ≈ 100 GB/s effective memory bandwidth ÷ weight size (dense) or scaled from the measured Qwen3 30B-A3B result (MoE). Prompt speed scaled from the measured Qwen3.6 35B-A3B result. Not measured on APEX LITE. Planning estimate — not measured
DeepSeek-R1 Distill 32B
DeepSeek · DenseQ419 GBFits with constraints
DeepSeek · DenseQ419 GBFits with constraints
- Developer
- DeepSeek
- Architecture
- Dense · 32B params
- Recommended use
- Reasoning
- Evidence
- Estimated — not yet tested
- Runtime / version
- Not recorded
- Context length
- Not recorded
- Runs / test date
- Not recorded
- Verification
- Calculated estimate: generation ≈ 100 GB/s effective memory bandwidth ÷ weight size (dense) or scaled from the measured Qwen3 30B-A3B result (MoE). Prompt speed scaled from the measured Qwen3.6 35B-A3B result. Not measured on APEX LITE. Planning estimate — not measured
- Note
- Needs reduced context or specialised configuration.
Llama 3.2 3B
Meta · DenseQ41.8 GBFits comfortably
Meta · DenseQ41.8 GBFits comfortably
- Developer
- Meta
- Architecture
- Dense · 3B params
- Recommended use
- Basic chat
- Evidence
- Estimated — not yet tested
- Runtime / version
- Not recorded
- Context length
- Not recorded
- Runs / test date
- Not recorded
- Verification
- Calculated estimate: generation ≈ 100 GB/s effective memory bandwidth ÷ weight size (dense) or scaled from the measured Qwen3 30B-A3B result (MoE). Prompt speed scaled from the measured Qwen3.6 35B-A3B result. Not measured on APEX LITE. Planning estimate — not measured
Llama 3.2 3B
Meta · DenseQ83.3 GBFits comfortably
Meta · DenseQ83.3 GBFits comfortably
- Developer
- Meta
- Architecture
- Dense · 3B params
- Recommended use
- Basic chat
- Evidence
- Estimated — not yet tested
- Runtime / version
- Not recorded
- Context length
- Not recorded
- Runs / test date
- Not recorded
- Verification
- Calculated estimate: generation ≈ 100 GB/s effective memory bandwidth ÷ weight size (dense) or scaled from the measured Qwen3 30B-A3B result (MoE). Prompt speed scaled from the measured Qwen3.6 35B-A3B result. Not measured on APEX LITE. Planning estimate — not measured
Llama 3.1 8B
Meta · DenseQ44.8 GBFits comfortably
Meta · DenseQ44.8 GBFits comfortably
- Developer
- Meta
- Architecture
- Dense · 8B params
- Recommended use
- General assistant
- Evidence
- Estimated — not yet tested
- Runtime / version
- Not recorded
- Context length
- Not recorded
- Runs / test date
- Not recorded
- Verification
- Calculated estimate: generation ≈ 100 GB/s effective memory bandwidth ÷ weight size (dense) or scaled from the measured Qwen3 30B-A3B result (MoE). Prompt speed scaled from the measured Qwen3.6 35B-A3B result. Not measured on APEX LITE. Planning estimate — not measured
Llama 3.1 8B
Meta · DenseQ88.8 GBFits comfortably
Meta · DenseQ88.8 GBFits comfortably
- Developer
- Meta
- Architecture
- Dense · 8B params
- Recommended use
- General assistant
- Evidence
- Estimated — not yet tested
- Runtime / version
- Not recorded
- Context length
- Not recorded
- Runs / test date
- Not recorded
- Verification
- Calculated estimate: generation ≈ 100 GB/s effective memory bandwidth ÷ weight size (dense) or scaled from the measured Qwen3 30B-A3B result (MoE). Prompt speed scaled from the measured Qwen3.6 35B-A3B result. Not measured on APEX LITE. Planning estimate — not measured
Gemma 3 4B
Google · DenseQ42.4 GBFits comfortably
Google · DenseQ42.4 GBFits comfortably
- Developer
- Architecture
- Dense · 4B params
- Recommended use
- Lightweight multilingual
- Evidence
- Estimated — not yet tested
- Runtime / version
- Not recorded
- Context length
- Not recorded
- Runs / test date
- Not recorded
- Verification
- Calculated estimate: generation ≈ 100 GB/s effective memory bandwidth ÷ weight size (dense) or scaled from the measured Qwen3 30B-A3B result (MoE). Prompt speed scaled from the measured Qwen3.6 35B-A3B result. Not measured on APEX LITE. Planning estimate — not measured
Gemma 3 4B
Google · DenseQ84.4 GBFits comfortably
Google · DenseQ84.4 GBFits comfortably
- Developer
- Architecture
- Dense · 4B params
- Recommended use
- Lightweight multilingual
- Evidence
- Estimated — not yet tested
- Runtime / version
- Not recorded
- Context length
- Not recorded
- Runs / test date
- Not recorded
- Verification
- Calculated estimate: generation ≈ 100 GB/s effective memory bandwidth ÷ weight size (dense) or scaled from the measured Qwen3 30B-A3B result (MoE). Prompt speed scaled from the measured Qwen3.6 35B-A3B result. Not measured on APEX LITE. Planning estimate — not measured
Gemma 3 12B
Google · DenseQ47.2 GBFits comfortably
Google · DenseQ47.2 GBFits comfortably
- Developer
- Architecture
- Dense · 12B params
- Recommended use
- Multilingual assistant
- Evidence
- Estimated — not yet tested
- Runtime / version
- Not recorded
- Context length
- Not recorded
- Runs / test date
- Not recorded
- Verification
- Calculated estimate: generation ≈ 100 GB/s effective memory bandwidth ÷ weight size (dense) or scaled from the measured Qwen3 30B-A3B result (MoE). Prompt speed scaled from the measured Qwen3.6 35B-A3B result. Not measured on APEX LITE. Planning estimate — not measured
Gemma 3 12B
Google · DenseQ813 GBFits comfortably
Google · DenseQ813 GBFits comfortably
- Developer
- Architecture
- Dense · 12B params
- Recommended use
- Multilingual assistant
- Evidence
- Estimated — not yet tested
- Runtime / version
- Not recorded
- Context length
- Not recorded
- Runs / test date
- Not recorded
- Verification
- Calculated estimate: generation ≈ 100 GB/s effective memory bandwidth ÷ weight size (dense) or scaled from the measured Qwen3 30B-A3B result (MoE). Prompt speed scaled from the measured Qwen3.6 35B-A3B result. Not measured on APEX LITE. Planning estimate — not measured
Gemma 3 27B
Google · DenseQ417 GBFits with constraints
Google · DenseQ417 GBFits with constraints
- Developer
- Architecture
- Dense · 27B params
- Recommended use
- Multilingual, higher quality
- Evidence
- Estimated — not yet tested
- Runtime / version
- Not recorded
- Context length
- Not recorded
- Runs / test date
- Not recorded
- Verification
- Calculated estimate: generation ≈ 100 GB/s effective memory bandwidth ÷ weight size (dense) or scaled from the measured Qwen3 30B-A3B result (MoE). Prompt speed scaled from the measured Qwen3.6 35B-A3B result. Not measured on APEX LITE. Planning estimate — not measured
- Note
- Needs reduced context or specialised configuration.
Ministral 3 3B
Mistral · DenseQ41.8 GBFits comfortably
Mistral · DenseQ41.8 GBFits comfortably
- Developer
- Mistral
- Architecture
- Dense · 3B params
- Recommended use
- Basic chat
- Evidence
- Estimated — not yet tested
- Runtime / version
- Not recorded
- Context length
- Not recorded
- Runs / test date
- Not recorded
- Verification
- Calculated estimate: generation ≈ 100 GB/s effective memory bandwidth ÷ weight size (dense) or scaled from the measured Qwen3 30B-A3B result (MoE). Prompt speed scaled from the measured Qwen3.6 35B-A3B result. Not measured on APEX LITE. Planning estimate — not measured
Ministral 3 8B
Mistral · DenseQ44.8 GBFits comfortably
Mistral · DenseQ44.8 GBFits comfortably
- Developer
- Mistral
- Architecture
- Dense · 8B params
- Recommended use
- Email, summaries
- Evidence
- Estimated — not yet tested
- Runtime / version
- Not recorded
- Context length
- Not recorded
- Runs / test date
- Not recorded
- Verification
- Calculated estimate: generation ≈ 100 GB/s effective memory bandwidth ÷ weight size (dense) or scaled from the measured Qwen3 30B-A3B result (MoE). Prompt speed scaled from the measured Qwen3.6 35B-A3B result. Not measured on APEX LITE. Planning estimate — not measured
Ministral 3 8B
Mistral · DenseQ88.8 GBFits comfortably
Mistral · DenseQ88.8 GBFits comfortably
- Developer
- Mistral
- Architecture
- Dense · 8B params
- Recommended use
- Email, summaries
- Evidence
- Estimated — not yet tested
- Runtime / version
- Not recorded
- Context length
- Not recorded
- Runs / test date
- Not recorded
- Verification
- Calculated estimate: generation ≈ 100 GB/s effective memory bandwidth ÷ weight size (dense) or scaled from the measured Qwen3 30B-A3B result (MoE). Prompt speed scaled from the measured Qwen3.6 35B-A3B result. Not measured on APEX LITE. Planning estimate — not measured
Ministral 3 14B
Mistral · DenseQ48.4 GBFits comfortably
Mistral · DenseQ48.4 GBFits comfortably
- Developer
- Mistral
- Architecture
- Dense · 14B params
- Recommended use
- Email, summaries
- Evidence
- Estimated — not yet tested
- Runtime / version
- Not recorded
- Context length
- Not recorded
- Runs / test date
- Not recorded
- Verification
- Calculated estimate: generation ≈ 100 GB/s effective memory bandwidth ÷ weight size (dense) or scaled from the measured Qwen3 30B-A3B result (MoE). Prompt speed scaled from the measured Qwen3.6 35B-A3B result. Not measured on APEX LITE. Planning estimate — not measured
Ministral 3 14B
Mistral · DenseQ815 GBFits comfortably
Mistral · DenseQ815 GBFits comfortably
- Developer
- Mistral
- Architecture
- Dense · 14B params
- Recommended use
- Email, summaries
- Evidence
- Estimated — not yet tested
- Runtime / version
- Not recorded
- Context length
- Not recorded
- Runs / test date
- Not recorded
- Verification
- Calculated estimate: generation ≈ 100 GB/s effective memory bandwidth ÷ weight size (dense) or scaled from the measured Qwen3 30B-A3B result (MoE). Prompt speed scaled from the measured Qwen3.6 35B-A3B result. Not measured on APEX LITE. Planning estimate — not measured
Estimates are preliminary planning ranges for weights only, not measured. Long contexts and concurrent users add KV cache. TOPS is not tokens per second.
How much AI fits in 32GB?
About 23 GB of 32 GB used; 9 GB free. Longer context grows the KV cache, and the OS and runtime take their share, so a model's file size is not its total memory use. Figures are reference estimates, not verified allocations.
Benchmarks
Real AI. Right on your desk.
Discover what local language models can do on APEX LITE.
Only models compatible with the 32GB configuration are shown. Speeds are calculated from published results on Core Ultra X7 358H / Arc B390 systems: Qwen3 30B-A3B (31 tok/s, Ollama) and Qwen3.6 35B-A3B (691 prompt / 32.7 generation tok/s, llama.cpp Vulkan) are third-party measurements; the rest are estimates marked “~” (about 100 GB/s effective memory bandwidth). None were measured on an APEX LITE unit. Open a row for sources and method.
Llama 3.2 3B
Estimated — not yet testedQ41.8 GB~691~56
Estimated — not yet testedQ41.8 GB~691~56
- Developer
- Meta
- Architecture
- Dense · 3B params
- Recommended use
- Basic chat
- Evidence
- Estimated — not yet tested
- Runtime / version
- Not recorded
- Context length
- Not recorded
- Runs / test date
- Not recorded
- Verification
- Calculated estimate: generation ≈ 100 GB/s effective memory bandwidth ÷ weight size (dense) or scaled from the measured Qwen3 30B-A3B result (MoE). Prompt speed scaled from the measured Qwen3.6 35B-A3B result. Not measured on APEX LITE. Planning estimate — not measured
Ministral 3 3B
Estimated — not yet testedQ41.8 GB~691~56
Estimated — not yet testedQ41.8 GB~691~56
- Developer
- Mistral
- Architecture
- Dense · 3B params
- Recommended use
- Basic chat
- Evidence
- Estimated — not yet tested
- Runtime / version
- Not recorded
- Context length
- Not recorded
- Runs / test date
- Not recorded
- Verification
- Calculated estimate: generation ≈ 100 GB/s effective memory bandwidth ÷ weight size (dense) or scaled from the measured Qwen3 30B-A3B result (MoE). Prompt speed scaled from the measured Qwen3.6 35B-A3B result. Not measured on APEX LITE. Planning estimate — not measured
Gemma 3 4B
Estimated — not yet testedQ42.4 GB~518~42
Estimated — not yet testedQ42.4 GB~518~42
- Developer
- Architecture
- Dense · 4B params
- Recommended use
- Lightweight multilingual
- Evidence
- Estimated — not yet tested
- Runtime / version
- Not recorded
- Context length
- Not recorded
- Runs / test date
- Not recorded
- Verification
- Calculated estimate: generation ≈ 100 GB/s effective memory bandwidth ÷ weight size (dense) or scaled from the measured Qwen3 30B-A3B result (MoE). Prompt speed scaled from the measured Qwen3.6 35B-A3B result. Not measured on APEX LITE. Planning estimate — not measured
Qwen3.6 35B-A3B
Third-party measurementQ421 GB69132.7
Third-party measurementQ421 GB69132.7
- Developer
- Qwen
- Architecture
- MoE (mixture of experts) · 35B params
- Recommended use
- Capable MoE assistant
- Evidence
- Third-party measurement
- Runtime / version
- Not recorded
- Context length
- Not recorded
- Runs / test date
- Not recorded
- Verification
- Third-party measurement — see source.
- Source
- grigio.org — llama.cpp on Intel Arc (Xiaomi Book Pro 14)
Core Ultra X7 358H, Arc B390, 30GiB unified memory, llama.cpp Vulkan, Qwen3.6-35B-A3B Q4_K_M fully offloaded to the GPU: 691 pp512, 32.7 tok/s generation. NoLlama OpenVINO INT4 reports 41.1 tok/s.
Third-party result on comparable hardware, not measured on a ZYREX unit.
Qwen3 30B-A3B
Third-party measurementQ418 GB~62831
Third-party measurementQ418 GB~62831
- Developer
- Qwen
- Architecture
- MoE (mixture of experts) · 30B params
- Recommended use
- Fast, capable assistant
- Evidence
- Third-party measurement
- Runtime / version
- Not recorded
- Context length
- Not recorded
- Runs / test date
- Not recorded
- Verification
- Third-party measurement — see source.
- Source
- MetriLLM — Qwen3-30B on Core Ultra X7 358H
Ollama 0.32.14, Core Ultra X7 358H: 31.0 tok/s generation. OpenVINO INT4 on the same CPU/GPU reaches 52.7 tok/s (NoLlama community report, 64GB LPDDR5X-8533).
Third-party result on comparable hardware, not measured on a ZYREX unit.
Qwen3-Coder 30B-A3B
Estimated — not yet testedQ418 GB~628~31
Estimated — not yet testedQ418 GB~628~31
- Developer
- Qwen
- Architecture
- MoE (mixture of experts) · 30B params
- Recommended use
- Coding
- Evidence
- Estimated — not yet tested
- Runtime / version
- Not recorded
- Context length
- Not recorded
- Runs / test date
- Not recorded
- Verification
- Calculated estimate: generation ≈ 100 GB/s effective memory bandwidth ÷ weight size (dense) or scaled from the measured Qwen3 30B-A3B result (MoE). Prompt speed scaled from the measured Qwen3.6 35B-A3B result. Not measured on APEX LITE. Planning estimate — not measured
Llama 3.2 3B
Estimated — not yet testedQ83.3 GB~384~30
Estimated — not yet testedQ83.3 GB~384~30
- Developer
- Meta
- Architecture
- Dense · 3B params
- Recommended use
- Basic chat
- Evidence
- Estimated — not yet tested
- Runtime / version
- Not recorded
- Context length
- Not recorded
- Runs / test date
- Not recorded
- Verification
- Calculated estimate: generation ≈ 100 GB/s effective memory bandwidth ÷ weight size (dense) or scaled from the measured Qwen3 30B-A3B result (MoE). Prompt speed scaled from the measured Qwen3.6 35B-A3B result. Not measured on APEX LITE. Planning estimate — not measured
GPT-OSS 20B
Estimated — not yet testedMXFP412 GB~576~28
Estimated — not yet testedMXFP412 GB~576~28
- Developer
- OpenAI
- Architecture
- MoE (mixture of experts) · 20B params
- Recommended use
- Everyday assistant
- Evidence
- Estimated — not yet tested
- Runtime / version
- Not recorded
- Context length
- Not recorded
- Runs / test date
- Not recorded
- Verification
- Calculated estimate: generation ≈ 100 GB/s effective memory bandwidth ÷ weight size (dense) or scaled from the measured Qwen3 30B-A3B result (MoE). Prompt speed scaled from the measured Qwen3.6 35B-A3B result. Not measured on APEX LITE. StorageReview measured 18.3 tok/s for gpt-oss:20b in an Ollama coding-agent test on a Core Ultra X7 358H laptop (an end-to-end workload, not a pure decode benchmark). Planning estimate — not measured
Gemma 3 4B
Estimated — not yet testedQ84.4 GB~288~23
Estimated — not yet testedQ84.4 GB~288~23
- Developer
- Architecture
- Dense · 4B params
- Recommended use
- Lightweight multilingual
- Evidence
- Estimated — not yet tested
- Runtime / version
- Not recorded
- Context length
- Not recorded
- Runs / test date
- Not recorded
- Verification
- Calculated estimate: generation ≈ 100 GB/s effective memory bandwidth ÷ weight size (dense) or scaled from the measured Qwen3 30B-A3B result (MoE). Prompt speed scaled from the measured Qwen3.6 35B-A3B result. Not measured on APEX LITE. Planning estimate — not measured
DeepSeek-R1 Distill 8B
Estimated — not yet testedQ44.8 GB~259~21
Estimated — not yet testedQ44.8 GB~259~21
- Developer
- DeepSeek
- Architecture
- Dense · 8B params
- Recommended use
- Reasoning
- Evidence
- Estimated — not yet tested
- Runtime / version
- Not recorded
- Context length
- Not recorded
- Runs / test date
- Not recorded
- Verification
- Calculated estimate: generation ≈ 100 GB/s effective memory bandwidth ÷ weight size (dense) or scaled from the measured Qwen3 30B-A3B result (MoE). Prompt speed scaled from the measured Qwen3.6 35B-A3B result. Not measured on APEX LITE. Planning estimate — not measured
Llama 3.1 8B
Estimated — not yet testedQ44.8 GB~259~21
Estimated — not yet testedQ44.8 GB~259~21
- Developer
- Meta
- Architecture
- Dense · 8B params
- Recommended use
- General assistant
- Evidence
- Estimated — not yet tested
- Runtime / version
- Not recorded
- Context length
- Not recorded
- Runs / test date
- Not recorded
- Verification
- Calculated estimate: generation ≈ 100 GB/s effective memory bandwidth ÷ weight size (dense) or scaled from the measured Qwen3 30B-A3B result (MoE). Prompt speed scaled from the measured Qwen3.6 35B-A3B result. Not measured on APEX LITE. Planning estimate — not measured
Ministral 3 8B
Estimated — not yet testedQ44.8 GB~259~21
Estimated — not yet testedQ44.8 GB~259~21
- Developer
- Mistral
- Architecture
- Dense · 8B params
- Recommended use
- Email, summaries
- Evidence
- Estimated — not yet tested
- Runtime / version
- Not recorded
- Context length
- Not recorded
- Runs / test date
- Not recorded
- Verification
- Calculated estimate: generation ≈ 100 GB/s effective memory bandwidth ÷ weight size (dense) or scaled from the measured Qwen3 30B-A3B result (MoE). Prompt speed scaled from the measured Qwen3.6 35B-A3B result. Not measured on APEX LITE. Planning estimate — not measured
Qwen3 8B
Estimated — not yet testedQ45 GB~259~20
Estimated — not yet testedQ45 GB~259~20
- Developer
- Qwen
- Architecture
- Dense · 8B params
- Recommended use
- Fast personal assistant
- Evidence
- Estimated — not yet tested
- Runtime / version
- Not recorded
- Context length
- Not recorded
- Runs / test date
- Not recorded
- Verification
- Calculated estimate: generation ≈ 100 GB/s effective memory bandwidth ÷ weight size (dense) or scaled from the measured Qwen3 30B-A3B result (MoE). Prompt speed scaled from the measured Qwen3.6 35B-A3B result. Not measured on APEX LITE. Planning estimate — not measured
Qwen3.5 9B
Estimated — not yet testedQ45.4 GB~230~19
Estimated — not yet testedQ45.4 GB~230~19
- Developer
- Qwen
- Architecture
- Dense · 9B params
- Recommended use
- Fast personal assistant
- Evidence
- Estimated — not yet tested
- Runtime / version
- Not recorded
- Context length
- Not recorded
- Runs / test date
- Not recorded
- Verification
- Calculated estimate: generation ≈ 100 GB/s effective memory bandwidth ÷ weight size (dense) or scaled from the measured Qwen3 30B-A3B result (MoE). Prompt speed scaled from the measured Qwen3.6 35B-A3B result. Not measured on APEX LITE. Planning estimate — not measured
Gemma 3 12B
Estimated — not yet testedQ47.2 GB~173~14
Estimated — not yet testedQ47.2 GB~173~14
- Developer
- Architecture
- Dense · 12B params
- Recommended use
- Multilingual assistant
- Evidence
- Estimated — not yet tested
- Runtime / version
- Not recorded
- Context length
- Not recorded
- Runs / test date
- Not recorded
- Verification
- Calculated estimate: generation ≈ 100 GB/s effective memory bandwidth ÷ weight size (dense) or scaled from the measured Qwen3 30B-A3B result (MoE). Prompt speed scaled from the measured Qwen3.6 35B-A3B result. Not measured on APEX LITE. Planning estimate — not measured
DeepSeek-R1 Distill 14B
Estimated — not yet testedQ48.4 GB~148~12
Estimated — not yet testedQ48.4 GB~148~12
- Developer
- DeepSeek
- Architecture
- Dense · 14B params
- Recommended use
- Reasoning
- Evidence
- Estimated — not yet tested
- Runtime / version
- Not recorded
- Context length
- Not recorded
- Runs / test date
- Not recorded
- Verification
- Calculated estimate: generation ≈ 100 GB/s effective memory bandwidth ÷ weight size (dense) or scaled from the measured Qwen3 30B-A3B result (MoE). Prompt speed scaled from the measured Qwen3.6 35B-A3B result. Not measured on APEX LITE. Planning estimate — not measured
Ministral 3 14B
Estimated — not yet testedQ48.4 GB~148~12
Estimated — not yet testedQ48.4 GB~148~12
- Developer
- Mistral
- Architecture
- Dense · 14B params
- Recommended use
- Email, summaries
- Evidence
- Estimated — not yet tested
- Runtime / version
- Not recorded
- Context length
- Not recorded
- Runs / test date
- Not recorded
- Verification
- Calculated estimate: generation ≈ 100 GB/s effective memory bandwidth ÷ weight size (dense) or scaled from the measured Qwen3 30B-A3B result (MoE). Prompt speed scaled from the measured Qwen3.6 35B-A3B result. Not measured on APEX LITE. Planning estimate — not measured
DeepSeek-R1 Distill 8B
Estimated — not yet testedQ88.8 GB~144~11
Estimated — not yet testedQ88.8 GB~144~11
- Developer
- DeepSeek
- Architecture
- Dense · 8B params
- Recommended use
- Reasoning
- Evidence
- Estimated — not yet tested
- Runtime / version
- Not recorded
- Context length
- Not recorded
- Runs / test date
- Not recorded
- Verification
- Calculated estimate: generation ≈ 100 GB/s effective memory bandwidth ÷ weight size (dense) or scaled from the measured Qwen3 30B-A3B result (MoE). Prompt speed scaled from the measured Qwen3.6 35B-A3B result. Not measured on APEX LITE. Planning estimate — not measured
Llama 3.1 8B
Estimated — not yet testedQ88.8 GB~144~11
Estimated — not yet testedQ88.8 GB~144~11
- Developer
- Meta
- Architecture
- Dense · 8B params
- Recommended use
- General assistant
- Evidence
- Estimated — not yet tested
- Runtime / version
- Not recorded
- Context length
- Not recorded
- Runs / test date
- Not recorded
- Verification
- Calculated estimate: generation ≈ 100 GB/s effective memory bandwidth ÷ weight size (dense) or scaled from the measured Qwen3 30B-A3B result (MoE). Prompt speed scaled from the measured Qwen3.6 35B-A3B result. Not measured on APEX LITE. Planning estimate — not measured
Ministral 3 8B
Estimated — not yet testedQ88.8 GB~144~11
Estimated — not yet testedQ88.8 GB~144~11
- Developer
- Mistral
- Architecture
- Dense · 8B params
- Recommended use
- Email, summaries
- Evidence
- Estimated — not yet tested
- Runtime / version
- Not recorded
- Context length
- Not recorded
- Runs / test date
- Not recorded
- Verification
- Calculated estimate: generation ≈ 100 GB/s effective memory bandwidth ÷ weight size (dense) or scaled from the measured Qwen3 30B-A3B result (MoE). Prompt speed scaled from the measured Qwen3.6 35B-A3B result. Not measured on APEX LITE. Planning estimate — not measured
Qwen3.5 9B
Estimated — not yet testedQ89.9 GB~128~10
Estimated — not yet testedQ89.9 GB~128~10
- Developer
- Qwen
- Architecture
- Dense · 9B params
- Recommended use
- Fast personal assistant
- Evidence
- Estimated — not yet tested
- Runtime / version
- Not recorded
- Context length
- Not recorded
- Runs / test date
- Not recorded
- Verification
- Calculated estimate: generation ≈ 100 GB/s effective memory bandwidth ÷ weight size (dense) or scaled from the measured Qwen3 30B-A3B result (MoE). Prompt speed scaled from the measured Qwen3.6 35B-A3B result. Not measured on APEX LITE. Planning estimate — not measured
Gemma 3 12B
Estimated — not yet testedQ813 GB~96~7.7
Estimated — not yet testedQ813 GB~96~7.7
- Developer
- Architecture
- Dense · 12B params
- Recommended use
- Multilingual assistant
- Evidence
- Estimated — not yet tested
- Runtime / version
- Not recorded
- Context length
- Not recorded
- Runs / test date
- Not recorded
- Verification
- Calculated estimate: generation ≈ 100 GB/s effective memory bandwidth ÷ weight size (dense) or scaled from the measured Qwen3 30B-A3B result (MoE). Prompt speed scaled from the measured Qwen3.6 35B-A3B result. Not measured on APEX LITE. Planning estimate — not measured
DeepSeek-R1 Distill 14B
Estimated — not yet testedQ815 GB~82~6.7
Estimated — not yet testedQ815 GB~82~6.7
- Developer
- DeepSeek
- Architecture
- Dense · 14B params
- Recommended use
- Reasoning
- Evidence
- Estimated — not yet tested
- Runtime / version
- Not recorded
- Context length
- Not recorded
- Runs / test date
- Not recorded
- Verification
- Calculated estimate: generation ≈ 100 GB/s effective memory bandwidth ÷ weight size (dense) or scaled from the measured Qwen3 30B-A3B result (MoE). Prompt speed scaled from the measured Qwen3.6 35B-A3B result. Not measured on APEX LITE. Planning estimate — not measured
Ministral 3 14B
Estimated — not yet testedQ815 GB~82~6.7
Estimated — not yet testedQ815 GB~82~6.7
- Developer
- Mistral
- Architecture
- Dense · 14B params
- Recommended use
- Email, summaries
- Evidence
- Estimated — not yet tested
- Runtime / version
- Not recorded
- Context length
- Not recorded
- Runs / test date
- Not recorded
- Verification
- Calculated estimate: generation ≈ 100 GB/s effective memory bandwidth ÷ weight size (dense) or scaled from the measured Qwen3 30B-A3B result (MoE). Prompt speed scaled from the measured Qwen3.6 35B-A3B result. Not measured on APEX LITE. Planning estimate — not measured
Qwen3.8 27B Dense
Estimated — not yet testedQ417 GB~77~5.9
Estimated — not yet testedQ417 GB~77~5.9
- Developer
- Qwen
- Architecture
- Dense · 27B params
- Recommended use
- Higher-quality assistant
- Evidence
- Estimated — not yet tested
- Runtime / version
- Not recorded
- Context length
- Not recorded
- Runs / test date
- Not recorded
- Verification
- Calculated estimate: generation ≈ 100 GB/s effective memory bandwidth ÷ weight size (dense) or scaled from the measured Qwen3 30B-A3B result (MoE). Prompt speed scaled from the measured Qwen3.6 35B-A3B result. Not measured on APEX LITE. Planning estimate — not measured
Gemma 3 27B
Estimated — not yet testedQ417 GB~77~5.9
Estimated — not yet testedQ417 GB~77~5.9
- Developer
- Architecture
- Dense · 27B params
- Recommended use
- Multilingual, higher quality
- Evidence
- Estimated — not yet tested
- Runtime / version
- Not recorded
- Context length
- Not recorded
- Runs / test date
- Not recorded
- Verification
- Calculated estimate: generation ≈ 100 GB/s effective memory bandwidth ÷ weight size (dense) or scaled from the measured Qwen3 30B-A3B result (MoE). Prompt speed scaled from the measured Qwen3.6 35B-A3B result. Not measured on APEX LITE. Planning estimate — not measured
DeepSeek-R1 Distill 32B
Estimated — not yet testedQ419 GB~65~5.3
Estimated — not yet testedQ419 GB~65~5.3
- Developer
- DeepSeek
- Architecture
- Dense · 32B params
- Recommended use
- Reasoning
- Evidence
- Estimated — not yet tested
- Runtime / version
- Not recorded
- Context length
- Not recorded
- Runs / test date
- Not recorded
- Verification
- Calculated estimate: generation ≈ 100 GB/s effective memory bandwidth ÷ weight size (dense) or scaled from the measured Qwen3 30B-A3B result (MoE). Prompt speed scaled from the measured Qwen3.6 35B-A3B result. Not measured on APEX LITE. Planning estimate — not measured
Choose your balance of speed and intelligence
Lower memory, often faster, possible quality trade-offs.
- Qwen3.6 35B-A3B: 21 GB, 32.7 tok/s generation (Third-party measurement)
- Qwen3 30B-A3B: 18 GB, 31 tok/s generation (Third-party measurement)
Speed and quality depend on model, runtime and hardware; no precision is always fastest.
Lower memory, often faster, possible quality trade-offs.
Higher precision and usually better quality retention; needs more memory.
Highest numerical precision (FP16/BF16) with far greater memory use.
Native GPT-OSS format; distinct from generic Q4 GGUF quantization.
Your workflow
Made for you. Ready for your workflow.
APEX LITE is designed around one primary active AI user.
Estimate: running tasks share the same hardware, so each gets a share of the single-task speed and response latency rises. APEX LITE is built for one main user with managed background jobs — not several users at full model speed.
Need AI for your whole team? See the APEX lineupAssistant
Meet your new everyday AI assistant.
Interactive demonstration with prepared responses — simulated, not live model inference.
Your AI coding partner. Always available.
def avg(xs):
    return sum(xs) / len(xs)
avg returns the arithmetic mean of a list. It will raise ZeroDivisionError for an empty list.
Prepared example (simulated). Good fits: coding-specialised MoE models such as Qwen3-Coder 30B-A3B at Q4, or a 8B–14B general model for faster replies.
Documents
Your files have answers. Just ask.
Contracts, reports, manuals, research papers and technical specifications — processed by a local retrieval pipeline.
Local mode can keep processing and storage under your control; actual privacy depends on the integrations and permissions you configure.
AI Agents
Give your AI a job to do.
A personal AI agent workstation for scheduled or sequential tasks.
Research, coding, tool execution, file-based workflows, task automation and supported messaging integrations.
Connects to a local Ollama / OpenAI-compatible endpoint (documented in Hermes' local setup guide). Use ~30B+ models for reliable tool calls.
Personal AI assistant with messaging-based interaction, tool-connected workflows and automated tasks.
Has a native Ollama provider; point it at the APEX endpoint.
Coding assistance, repository investigation and software development workflows.
Uses any OpenAI-compatible or Ollama endpoint via its LLM settings. Needs a strong coding model and a sandbox.
Task automation, API integrations, scheduled workflows and local inference triggers.
Ollama chat-model and OpenAI-compatible nodes can target the local APEX endpoint.
Advanced options for orchestrating specialized workers. Best with a capable model and careful job limits.
Works with any chat model, including ChatOllama or OpenAI-compatible servers on APEX.
How an agent works on APEX LITE
Example jobs
Best for one main user with controlled background jobs: use a job queue, a low maximum of concurrent jobs, model reuse, memory-aware scheduling and task priorities. Agent actions require appropriate permissions.
Intel AI
Optimized for Intel AI.
Optimized AI inference across supported CPU, GPU and NPU hardware, and compatible model deployment.
GPU programming and acceleration infrastructure for the Intel compute ecosystem.
Acceleration via SYCL or Vulkan on the integrated graphics where available, with CPU inference as a fallback.
Easy local model apps that serve an OpenAI-compatible endpoint.
Intel's tuned PyTorch extension for running LLMs, where supported.
Not every runtime uses the NPU automatically, and NPU TOPS are not a measure of LLM generation speed.
Setup
Your first local AI. Made simple.
01 · Start APEX LITE
Connect power, display, keyboard and network if needed.
02 · Install AI software
Choose an inference application such as Ollama or LM Studio, or an OpenVINO / llama.cpp build.
03 · Select a model
Pick a model that fits the device's memory — see the compatibility explorer above.
04 · Start chatting
Run your model locally and confirm the real tok/s on your machine.
05 · Add your documents
Connect authorized local files to a retrieval pipeline.
06 · Enable an AI agent
Point Hermes, OpenClaw or another tool at the local model endpoint.
07 · Customize your workspace
Configure models, storage, permissions and task workflows.
Connectivity
Small workstation. Plenty of connections.
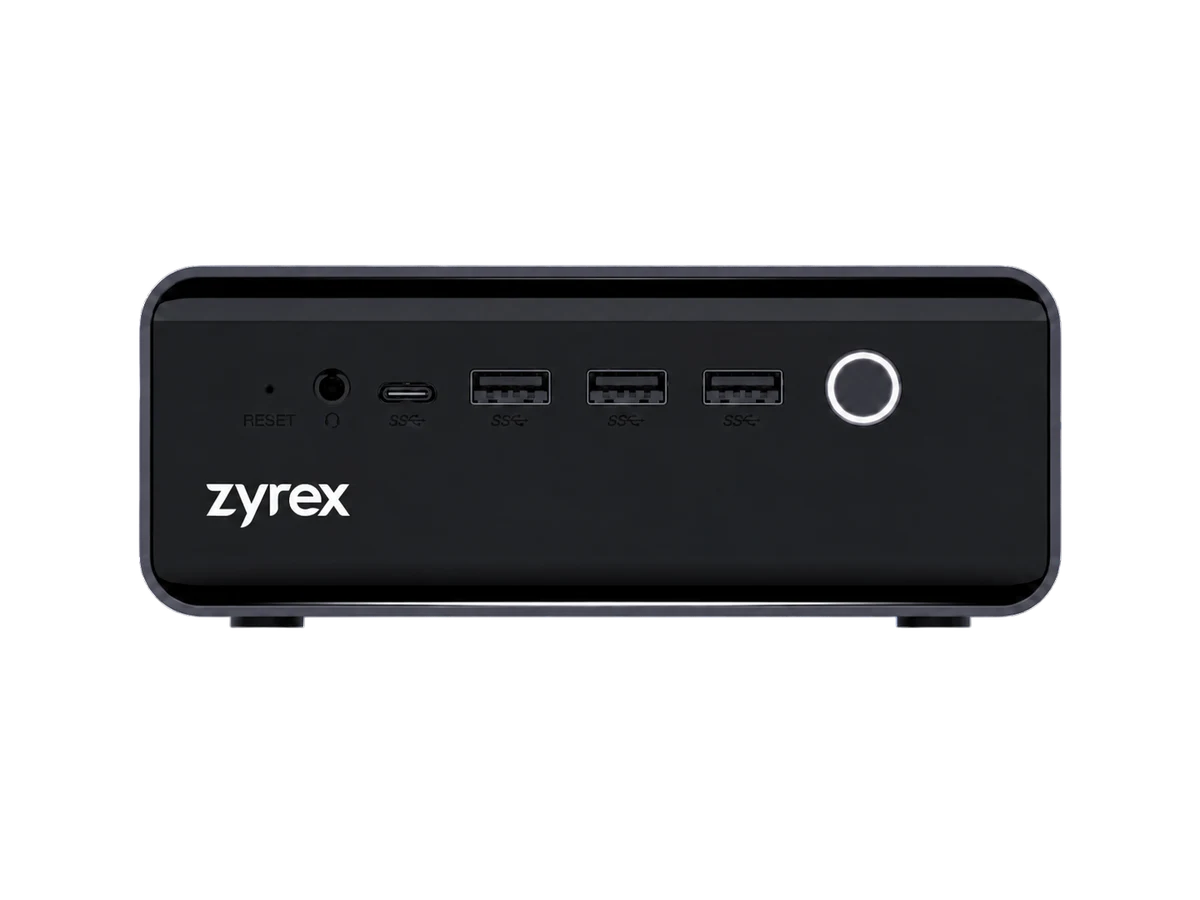
Select a port on the photo.
Ports follow the supplied product reference and photographs. The rear USB-C ports are listed as Thunderbolt 4 per the reference; confirm against final hardware before release. Wi-Fi 6E, Bluetooth 5.2, 150W adapter and VESA mounting support complete the connectivity.
Your own library of AI models
Three M.2 slots (reference 3 × 1TB, up to 2TB per slot, pending validation). Installed models can be switched without re-downloading them. Storage capacity is separate from the memory available for inference; the split shown is an example.
Recommendation
Find your perfect local AI model.
- Precision: MXFP4
- Estimated memory: 12 GB of ~22 GB usable (Fits comfortably)
- Speed: ~28 tok/s (calculated estimate)
- Software: Ollama, LM Studio, or llama.cpp (SYCL / Vulkan); OpenVINO where supported
- Longer context (8K) grows the KV cache and slows responses.
A rule-based suggestion from the estimated dataset — no quality scores are implied.
Contact salesAI Pribadi Anda. Tepat di Meja Anda.
Tersedia untuk pesanan bisnis & pemerintah
Sekilas

Galeri
Spesifikasi Teknis
Semua yang ada di dalam ZYREX APEX LITE Mini AI Workstation.
- Processor
- Intel Core Ultra X7 358H processor
- AI software: Intel OpenVINO, oneAPI, llama.cpp (SYCL / Vulkan), IPEX-LLM, Ollama, LM Studio
- Memory
- 32GB LPDDR5X memory (reference configuration)
- Storage
- 3 × M.2 SSD slots (reference 3 × 1TB, up to 2TB per slot, subject to validation)
- Graphics
- Integrated Intel graphics, Intel AI acceleration and Intel NPU
- Ports
- 3 × USB-A (10Gbps), 1 × USB-C, 1 × headphone/mic jack, power button, reset
- Display
- Rear ports: 2 × Thunderbolt 4, 2 × USB-A, 1 × HDMI 2.0, 1 × DisplayPort 2.0, 2 × 2.5GbE LAN, 1 × DC-in
- Connectivity
- Wi-Fi 6E, Bluetooth 5.2, dual 2.5GbE LAN
- Power
- 150W adapter
- VESA Mount
- VESA mounting support
- Feature
- Reference specifications — final specifications confirmed before release